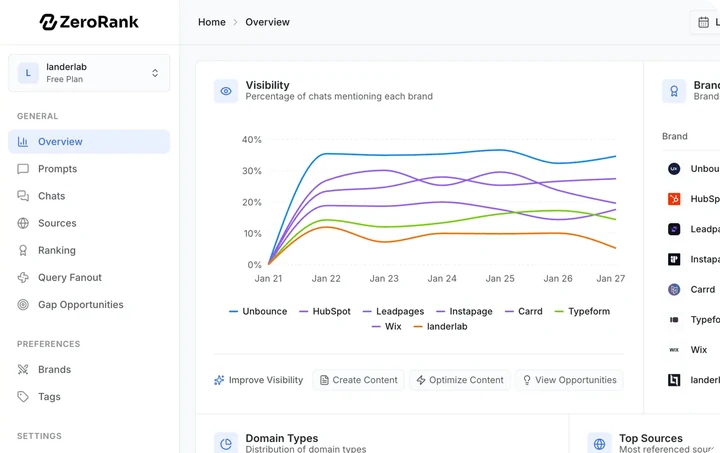
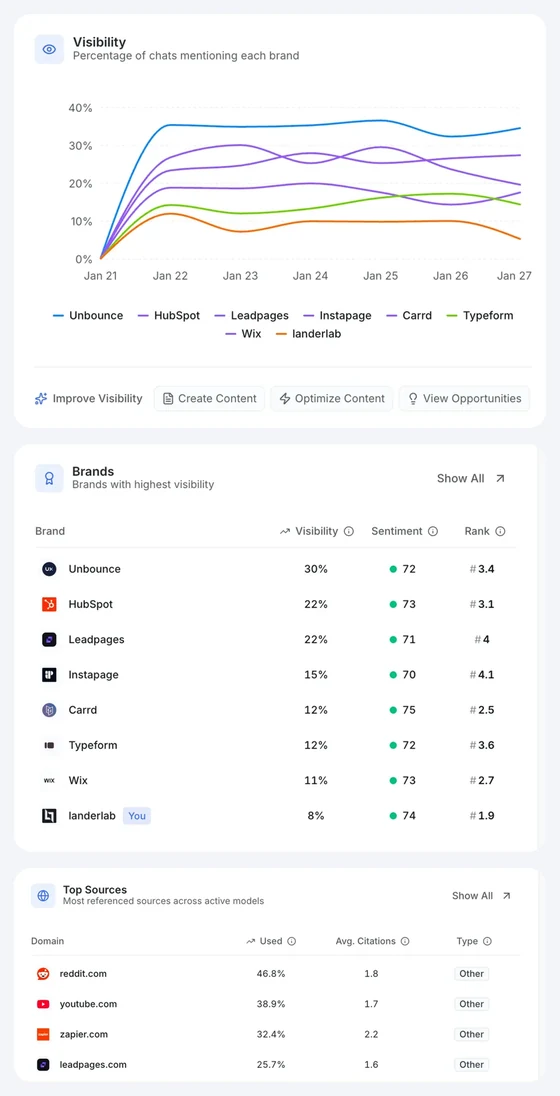
The same questions, on the same schedule, across every model — so a change on Tuesday means the same thing as a change in March.
AdPlexity · Ad intelligence
From checking prompts by hand to having everything in one place
The team was asking assistants about its own category manually, in a spreadsheet, and getting a different answer every time. The hours went back into the work that moved the number — which improved by over 40%.
40%+visibility improvement
60prompts tracked daily
3 monthsto a stable lead
hourssaved every week
The problem
A spreadsheet, and a different answer every time
AdPlexity knew AI answers mattered for competitive ad research, so somebody checked. By hand. Across a handful of assistants, a few times a week, pasting results into a sheet.
It did not work, for a reason that has nothing to do with effort: answers shift with phrasing, session and day. A single check tells you almost nothing, and a hand-kept sheet cannot tell a real change from noise.
It was also expensive in the only currency that matters for a small marketing team — hours that were not being spent on the pages that would have changed the result.
What we changed
Replace the checking, then work the list
The tracking paid for itself in time before it paid for itself in visibility.
Two different wins that need two different fixes. The sheet had been counting them as one thing.
Six changes across on-page copy, structured data and the third-party listings assistants quoted, in order of the prompts each touched.
The before and after for each prompt, with the ship date marked — the reporting that used to be assembled by hand.
The result
Over 40% more visible, and hours back
The manual checking stopped in week one. The visibility moved over the quarter.
Before
- Hours a week spent checking prompts manually.
- No way to tell a real change from session noise.
- Mentions and citations counted as one thing.
- Reporting assembled by hand from screenshots.
After
- Visibility improved by over 40%.
- Everything in one place, refreshed daily.
- Mentions and citations tracked separately, per model.
- Reporting that exports itself, with the answers behind it.
We went from manually checking prompts for hours to having everything in one place. Visibility improved by over 40%.
 Guido SilbertMarketing & Growth at AdPlexity
The method
The same four things, in every story
Different companies, different problems — but the sequence that moved the number was the same one, and it is the one you get on day one.
- Week onePrompt set built60Re-runDailyPlatforms17
Measure first. A real prompt set, on a schedule, so a change means something.
- best AI visibility trackerDailyChatGPTGeminiPerplexityClaude
Separate the two wins. Being named and being cited need different fixes.
Watch the rivals. Share of voice on the prompts that decide the category.
- Fix shippedMar 14 · 3 prompts
Keep the proof. Before and after on the prompt that failed, with the ship date on it.